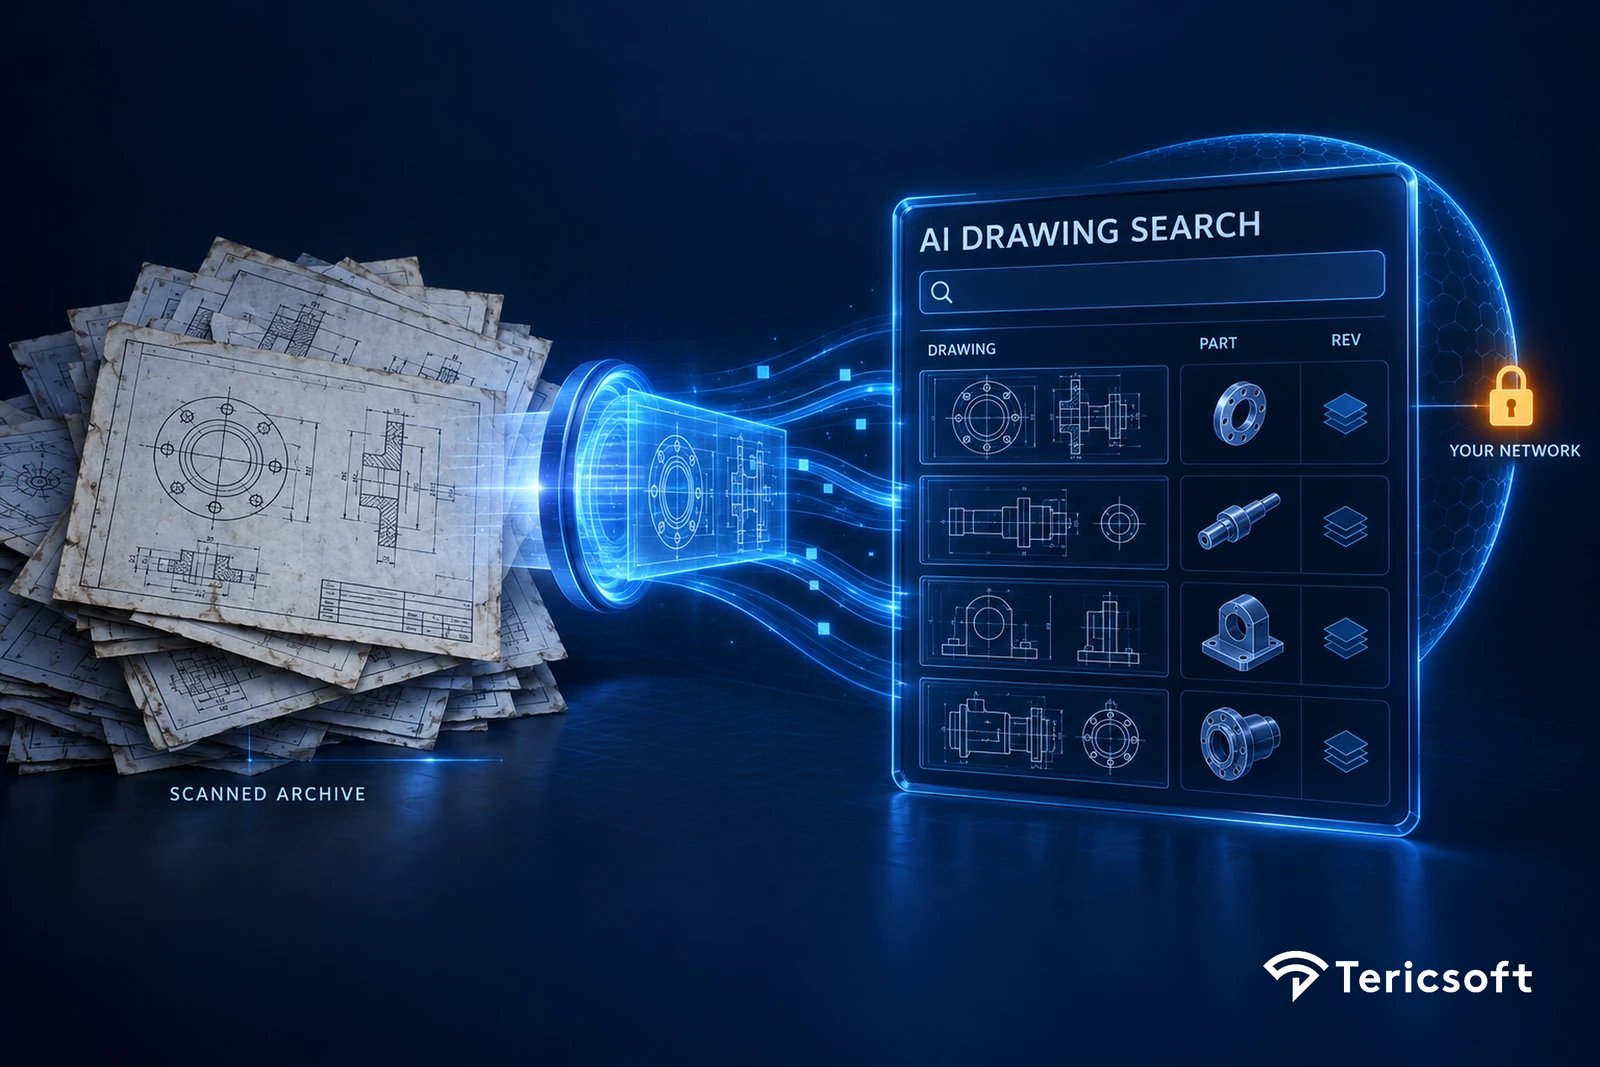
Your company may hold hundreds of thousands of drawings and still be unable to find one. Why? Because a scanned drawing is a picture, not text, and text search cannot read it.
A large engineering company can hold hundreds of thousands of drawings and still be unable to find one. The drawing numbers exist, the part numbers exist, the specifications exist, and none of it is searchable, because a scanned drawing is a picture, not text. The knowledge is there. It is simply invisible to every tool built to search words. When finding a single drawing takes an engineer hours of manual digging, the archive has quietly become a liability instead of an asset.
We recently built an AI search platform over an archive of more than 400,000 engineering drawings for a global engineering enterprise, with one hard constraint: the drawings could never leave the company's own network. This article is what that work taught us about why engineering archives resist search, and what it actually takes to fix them.
Why an engineering archive is invisible to search
Most engineering archives were never designed to be searched. Decades of drawings were produced on paper, scanned, and stored as image files, often bundled into long multi-page documents with cover sheets, revisions, and specifications mixed together. The information an engineer needs lives inside the image: in title blocks, part callouts, dimensions, revision tables, and symbols. To a text search engine, all of it is a flat picture with nothing to index. No amount of folder hierarchy or drawing management software fixes that, because the problem is not how the files are organized, it is that their content cannot be read.
So engineers fall back on what they have: a colleague who remembers where things are, a naming convention that three generations of staff interpreted differently, and manual browsing. That works until the archive grows, until formatting drifts, or until the person who remembered everything retires. At that point the cost is not just lost time per lookup. It is an organizational knowledge risk, where critical engineering IP is effectively locked away from the people who need it.
Why plain OCR does not solve it
The obvious fix is optical character recognition: run OCR over every scan, extract the text, and search that. It helps, and it is not enough. OCR reads characters; it does not understand that a number in a title block is a drawing number, the same digits in a callout are a part reference, and a value in a revision table is a date. A drawing is layout, symbols, and spatial relationships as much as it is text, and flattening it to a stream of characters throws away most of the meaning.
Recent research makes the same point. BLUEPRINT, a multimodal retrieval system for complex engineering drawings, detects the distinct regions of a drawing, runs vision-language OCR restricted to each region, normalizes the identifiers it finds, and fuses keyword and meaning-based retrieval. On a benchmark of thousands of files it beat the strongest vision-language baseline, which is a precise way of saying that understanding a drawing takes vision and language together, not characters alone. Real drawing search is a retrieval problem over images and meaning, not a text-extraction problem.
Engineers search three different ways
Once the content is understood, the next discovery is that there is no single way engineers want to search. There are three, and a usable platform has to serve all of them.
The first is keyword search: the engineer knows the drawing number or part code and wants the exact match instantly. The second is semantic search: the engineer does not know the number but knows what the part does, or wants every drawing similar to one in front of them. The third is conversational search: the engineer asks a plain-language question and expects the archive to answer from what it holds. Build only keyword search and you have rebuilt the old index with better plumbing. Serve all three on one platform and the archive finally behaves like knowledge rather than storage.
The unglamorous part: finding the drawing in the mess
The model that reads a drawing is the part people talk about. The part that decides whether the project works is the pipeline that gets a clean drawing to that model in the first place. Legacy files do not arrive as neat single drawings. They arrive as sprawling documents where drawing pages sit among scanned memos, cover sheets, and specifications, in inconsistent formats accumulated over decades.
So the real work is a document-processing pipeline that screens every file, identifies which pages are actually drawings, extracts the information from each, structures it into consistent fields, and indexes it for fast retrieval. This is unglamorous, and it is where most of the engineering effort goes. It is also the part of engineering document management that storage systems were never built to handle: not holding the files, but understanding what is inside them. An archive is only as searchable as its messiest file, and the pipeline is what tames the mess at scale.
The constraint that rewrites the architecture: the data cannot leave
For an engineering company, its drawings are crown-jewel intellectual property, and that single fact rewrites the whole design. Most AI search products assume your documents can be sent to their cloud to be processed. For proprietary engineering IP, that assumption is a non-starter, and it is the first question a serious security team asks.
The platform we built runs entirely inside the client's own secure network, reachable only by authorized employees over the company VPN. Processing is stateless, zero data is retained by any AI provider, and nothing is used to train external models. Data sovereignty is not a feature bolted on at the end; it is the constraint that decides which models you can use, where they run, and how the pipeline is built. An AI search platform an engineering enterprise can actually deploy is one where the intelligence comes to the data, never the other way around.
What building this taught us
Across the engagement, more than 400,000 drawings became searchable through three unified modes, keyword, semantic, and conversational, with the entire platform running 100 percent inside the client's own network and zero data leaving it. The headline is the number of drawings. The lesson is everything underneath it.
The AI model that reads a drawing was the smallest part of the problem. The wins were the screening pipeline that found real drawings inside messy legacy files, the three-mode search that matched how engineers actually look for things, and the in-network deployment that let a security-conscious enterprise say yes. Make those three right and a dead archive turns into a living, searchable asset. Get any one wrong and you have a demo, not a system.
Key takeaways
- A scanned archive is invisible to search. Drawing numbers and specs exist, but as images, so text search finds nothing and engineers fall back on manual lookups and fading institutional memory.
- OCR alone is not enough. A drawing is layout, symbols, and spatial meaning; understanding it takes vision and language together, not character extraction.
- Engineers search three ways. Keyword, semantic, and conversational search are different needs, and a real platform serves all three on one archive.
- Data sovereignty rewrites the architecture. For crown-jewel engineering IP, the platform must run inside the client's own network with zero provider retention, so the intelligence goes to the data.
About Tericsoft
Tericsoft builds AI systems that run where the data has to stay. For this engagement that meant an engineering-drawing search platform deployed entirely inside the client's own network, turning a scanned archive no tool could read into a knowledge base engineers query in seconds. We are an AI-first technology partner, and our work tends to start exactly where off-the-shelf AI stops: messy legacy data, hard security constraints, and a business outcome that only counts if the system actually ships into production. If decades of your own knowledge are locked in files nobody can search, that gap between having the data and being able to use it is the problem we engineer for.

AI identifies the drawing pages in each file, reads text and symbols with vision-language models, structures the data, and indexes it.
Because a scanned drawing is an image, not text. Numbers and specs are visible to a person but invisible to a text index until extracted.
No. OCR reads characters but misses layout, symbols, and spatial meaning. Accurate drawing search needs vision and language together.
Yes. It can run entirely inside your own network over your VPN, with stateless processing and zero data retained by AI providers.
Semantic search finds drawings by meaning or similarity; conversational search answers a plain-language question. Both go beyond keywords.